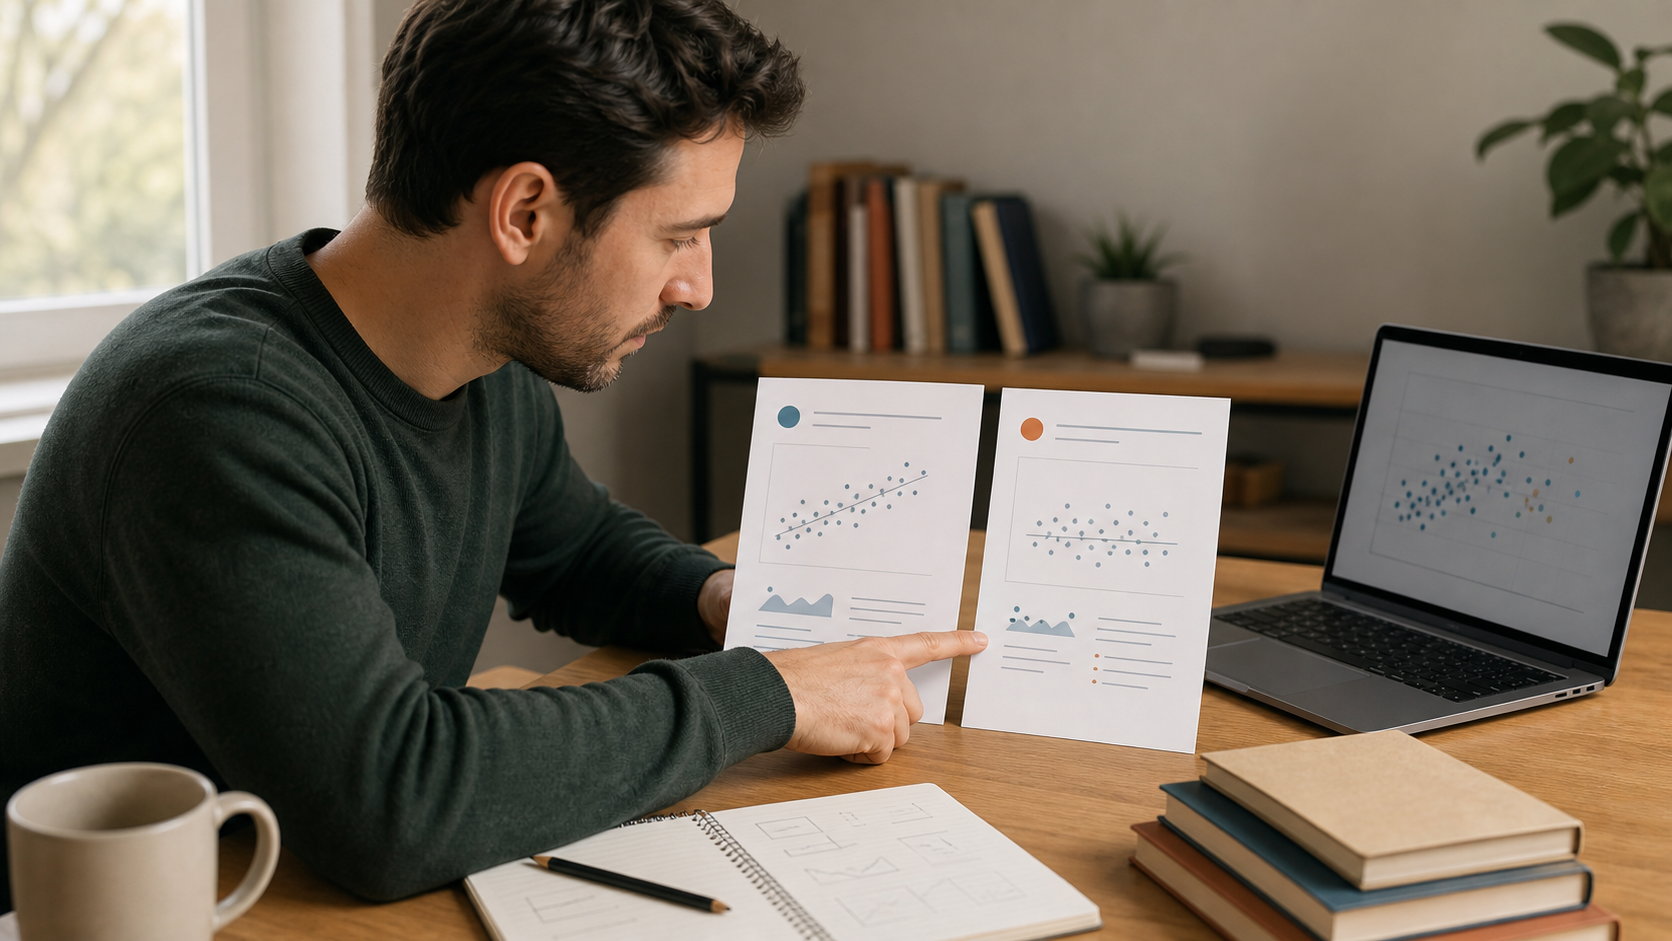
Two scatterplots sit side by side. The first rises gently, with its points packed close to a line. The second rises steeply, but its points are widely scattered. Asked which relationship is stronger, a learner points to the steeper graph. The answer feels visual and immediate. It is also based on the wrong feature.
A direct explanation can correct the sentence: slope describes the rate of change, while correlation describes the direction and strength of a linear association. Yet the learner may repeat that distinction without seeing it in the next graph. Contrasting cases create a different kind of lesson. They place carefully chosen examples together so that a relevant difference becomes hard to ignore, then require the learner to explain what that difference changes.
AI can produce pairs, variations, tables, and questions quickly. Its speed is helpful only when the cases are designed around a trusted learning target and checked before use. The workflow below keeps the answer covered long enough for noticing to happen, makes every visual traceable to data, and ends with a new case that the learner must judge without the original pair.
Put the pair on the table before the explanation
Case comparison is not simply reading two examples. The cases must be available together, the learner must attend to their relationship, and the task must ask what is shared and what differs. In a 2013 meta-analysis covering 57 experiments and 336 tests, Louis Alfieri, Timothy Nokes-Malach, and Christian Schunn found better learning from case-comparison activities than from several other forms of case study and instruction. The average effect did not mean that every comparison worked equally well; the design of the activity was one of the review's central concerns.
Experimental work in algebra shows why joint attention matters. Bethany Rittle-Johnson and Jon Star randomly assigned 70 seventh-grade students to compare alternative equation-solving methods or study the same methods one at a time. The comparison group made larger gains in procedural knowledge and flexibility, with comparable conceptual gains. The lesson is narrower than 'more examples are better': placing related methods together can reveal choices that sequential study leaves implicit.
Keep the first minute quiet. Show the pair, hide the labels and explanation, and ask the learner to write three observations and one tentative rule. AI should not announce the pattern before the learner has something to compare with it. The first imperfect observation becomes evidence of what the learner actually noticed.
Choose a difference that carries the lesson
Start from one target statement taken from a course source. For this session: slope describes how much predicted y changes for a one-unit change in x, while the correlation coefficient describes the direction and strength of a linear association. OpenStax also warns that correlation does not imply causation and that a regression model should be checked against the plotted pattern and residuals. Those facts define what the examples may teach.
Now decide which comparison will expose the likely confusion. Pair A can have a modest positive slope with points close to its fitted line. Pair B can have a steeper positive slope with points more widely dispersed. The useful contrast is not that one graph looks busier or uses a brighter color. It is that steepness and tightness move in different directions, forcing the learner to decide which visual feature belongs to which statistic.
The U.S. Institute of Education Sciences describes contrasting cases as examples with systematic variation that can help learners notice quantitative structure. Its research summary also notes that selecting the right cases is often done by intuition. Treat case construction as a small design problem: name the target relation, the misconception, the dimension that changes, and the details that must stay comparable.
- Target relation: the exact rule or distinction the learner should be able to use.
- Likely cue: the visible but misleading feature the learner may follow.
- Diagnostic contrast: the feature that changes across the pair to challenge that cue.
- Controls: axes, variable meanings, sample size, and presentation choices that should not distract from the contrast.
Build a comparison grid with the answer covered
A four-row grid is enough for the first pass. The columns are Case A, Case B, same, and different. The rows are visible pattern, fitted-line slope, spread around the line, and claim the graph supports. The learner fills only what can be observed or calculated. The rule row stays folded or hidden.
Ask comparison questions in an order that moves from perception to explanation: What do both plots have in common? Which line is steeper? In which plot do the points stay closer to the line? Which feature would change slope? Which feature would change the magnitude of correlation? The learner should point to a visible or numerical feature for every answer.
A 2015 fraction-division experiment provides an important caution. Cristina Durkin and Rittle-Johnson found that prompts to self-explain supported conceptual learning, while encouragement to compare without explanation prompts did not produce the same benefit in that setting. Do not assume that proximity does the teaching. Require a because statement: 'I judge Case A as more strongly correlated because its points cluster more tightly around a straight line, not because its line is steeper.'
Give AI the construction job, not the noticing job
Weak prompt: "Teach me correlation with two examples." The assistant can choose any examples, explain the answer immediately, and change several features at once. A polished response may leave no decision for the learner to make.
Improved prompt: "I am learning to distinguish the steepness of a regression line from the strength of a linear association. Using the supplied OpenStax definitions, create two small synthetic datasets with the same x values and sample size. Both should show positive linear association. Case A should have a shallower fitted slope and points close to the line; Case B should have a steeper fitted slope and more scatter. Keep the x- and y-axis ranges identical. Return the two data tables first, with neutral labels only. Then place the calculated slope and correlation for each case under a clearly marked ANSWER KEY that I can hide. Do not explain the rule until I send my comparison. State that the data are synthetic and round displayed values to two decimals."
Expected output: the visible portion contains two tables called Case A and Case B, using the same x values. The hidden key reports a smaller slope but a correlation closer to 1 for Case A, and a larger slope but a weaker positive correlation for Case B. It also includes enough calculation detail to reproduce both values. The learner plots the tables, records a rule, and only then opens the key.
The prompt does not make the output correct. It makes errors easier to detect. Synthetic labels prevent a real-world story from suggesting causation, common axes prevent scale tricks, and reproducible values allow an independent check. If the assistant cannot produce a clean pair after two attempts, use instructor examples or construct the cases in a spreadsheet instead of polishing a broken prompt.
Run a twenty-five-minute compare-and-test session
Spend three minutes writing the target and the misconception in your own words. Spend five minutes plotting the two datasets without opening the key. Spend five minutes filling the comparison grid. Then spend four minutes writing one because statement and one prediction: if the scatter increased but the slope stayed similar, what should happen to the magnitude of correlation?
Open the answer key for four minutes. Check each disagreement against the data rather than accepting the assistant's explanation. If your graph uses different axis limits, redraw it before judging the visual. Use the final four minutes for a third dataset with no labels. Estimate which statistic should change, calculate or look up the answer, and write the smallest correction needed.
This order resembles the preparation-for-future-learning logic in Daniel Schwartz and Taylor Martin's statistics studies: an activity can prepare learners to notice and use a later explanation rather than trying to replace instruction. The goal is not to invent the formal definition from nothing. It is to make the definition answer a question the learner has already encountered in the cases.
- 0-3 minutes: write the target and likely misleading cue.
- 3-8 minutes: plot both datasets with the key hidden.
- 8-13 minutes: complete the same/different grid.
- 13-17 minutes: state a rule and make a changed-case prediction.
- 17-21 minutes: reveal and independently check the key.
- 21-25 minutes: judge a fresh transfer case.
Catch pairs that teach the wrong contrast
A confounded pair changes slope, scatter, axis range, sample size, and variable meaning together. The learner cannot know which difference carries the rule. Repair it by holding obvious display conditions constant and listing every intentional change. Real datasets are often messy, so use a clean synthetic pair to isolate the idea and a real dataset later to test whether it survives noise.
Answer leakage happens when titles such as 'strong correlation' or a helpful caption reveal the classification. Explanation leakage is quieter: the assistant adds a preamble that tells the learner where to look. Request neutral labels and put the key after a delimiter. A hidden answer is only hidden if the plotting tool, filename, legend, and surrounding text do not disclose it.
A decorative difference can also hijack attention. Color, aspect ratio, point size, and cropped axes can make one relationship appear more dramatic. A numerical mismatch is more serious: the displayed graph may not correspond to the table or the reported statistics. Finally, a pair can be too easy. If one graph is a perfect line and the other is random noise, the learner may succeed without distinguishing slope from strength. The contrast should be visible enough to reason about but close enough to require the target rule.
Check the data behind the visual
Verification begins with provenance. Mark generated datasets as synthetic, preserve the exact table, and record the prompt or construction rule. Replot both cases in a spreadsheet, statistics package, or another calculator. Confirm the sample size, x values, axis limits, fitted slope, and correlation coefficient. If a reported number cannot be reproduced, reject the key and do not build the lesson around it.
Next, inspect whether the intended interpretation is allowed. OpenStax recommends looking at the scatterplot and residual pattern when deciding whether a linear model is reasonable. A single correlation coefficient can conceal curvature, outliers, or changing variance. Do not let a convenient r value overrule the graph, and do not turn association into a causal claim.
The final check is editorial: ask whether a learner who has not seen the answer can identify the intended contrast. Have a second person describe what changed, or return to the pair after a day with the labels removed. If attention goes first to an accidental feature, redesign the pair. Verification is not only recalculating numbers; it is checking that the materials invite the intended decision.
Use a third case as the exit ticket
The third case should not be a duplicate with new colors. Change the surface details while preserving the decision. For example, provide a scatterplot with a negative, steep slope and points tightly clustered around the line. Ask for the sign of the association, a judgment about its strength, and a separate description of the slope. Then ask what additional evidence would be needed before making a causal claim.
Do not show Case A or Case B during this test. The learner should state the rule in target language, apply it, and point to evidence in the fresh graph. A correct label without a reason may be recognition. A defensible reason shows that the learner can coordinate the visible pattern with the statistic it represents.
If the transfer answer fails, return to one decision, not the entire lesson. A learner who confuses direction with strength needs a different contrast from a learner who mistakes steepness for strength. Save the failed judgment, build one new pair that isolates it, and test again later without the old explanation on screen.
Keep only the rule that survives new cases
A useful contrasting-case session leaves a compact record: the source-backed target, the pair and its data, the learner's first observation, the verified answer key, and the third-case result. It does not need a long transcript. The important trail is what the learner noticed, what evidence changed the judgment, and whether the revised rule traveled.
AI earns a place in this workflow by making controlled variations inexpensive. It can propose a near miss, remove labels, create another surface context, and format a reproducible key. The source defines the concept, the data constrain the example, and the learner performs the comparison. Those roles should remain visible.
The exit condition is simple: close the original pair and explain why a steeper line need not mean a stronger linear association, then judge a fresh graph correctly and verify the calculation. When the rule survives that change, the cases have stopped being pictures to remember and become evidence the learner can reason with.
Continue learning on JoyfulGrid
Frequently asked questions
How many contrasting cases should I use at once?
Start with two cases that isolate one important distinction, then use one fresh case for transfer. Add more only when each case tests a named feature; a large gallery can hide the comparison the learner is meant to make.
Should the cases use real or synthetic data?
Synthetic data are useful for isolating one relationship, provided they are clearly labeled and reproducible. Follow with a real, sourced dataset when the goal is to handle noise, context, sampling, or causal limits.
Can I trust the answer key generated by AI?
No. Replot the supplied data and recalculate the key with a trusted tool or course method. Reject any graph, slope, correlation, or explanation that does not match the preserved table and source definition.
What if the learner notices an unintended difference first?
Treat that observation as a design test. Remove or control the distracting feature, state which dimension is intentional, and rerun the comparison without revealing the final rule.
Sources
- Learning Through Case Comparisons: A Meta-Analytic ReviewEducational Psychologist
Used for the meta-analysis of 57 experiments and 336 tests, the overall case-comparison finding, and the emphasis on how comparison activities are implemented.
- Does Comparing Solution Methods Facilitate Conceptual and Procedural Knowledge?Journal of Educational Psychology via ERIC
Used for the randomized study of 70 seventh-grade students comparing algebra methods jointly or studying them sequentially.
- How Do Contrasting Cases and Self-Explanation Promote Learning? Evidence from Fraction DivisionLearning and Instruction
Used for evidence that self-explanation prompts supported conceptual learning and that comparison without explanation prompts was insufficient in this study.
- Designing Contrasting Cases for Inductive LearningU.S. Institute of Education Sciences
Used for the systematic-variation framing, the role of case selection, and the distinction between conceptual transfer and procedural fluency measures.
- Inventing to Prepare for Future Learning: The Hidden Efficiency of Encouraging Original Student Production in Statistics InstructionCognition and Instruction via Stanford AAA Lab
Used for the preparation-for-future-learning framing from two studies of descriptive-statistics instruction with ninth-grade students.
- The Regression EquationOpenStax Introductory Statistics 2e
Used for the definitions and checks involving scatterplots, slope, correlation, residuals, linear-model fit, prediction limits, and the warning that correlation does not imply causation.